About Reva
Reva is a high-performance interfacing server between clients and storage backends. Reva is a powerful and customizable tool, because of which it may be hard to get started: there are many options and ways to set Reva up. This guide serves as an introduction to getting started with Reva: it explains some of the deployment options, as well as the most important configuration settings. To get started, download a copy of the latest version of Reva here. The downloads list two binaries: revad and reva. revad is the actual server, so this is the one you will want to use for your setup. reva is a CLI tool that you can use to connect to revad and perform actions.
Deployment
Reva can be containerized and can be run in Kubernetes clusters. At CERN however, we want to squeeze out the maximum possible performance, which means we deploy Reva on bare-metal machines using systemd. Reva itself has a number of deployment options, the most important one being how many daemons to run. Reva consists of a number of microservices, which can run under the same process or under different processes. Our deployment looks like this:
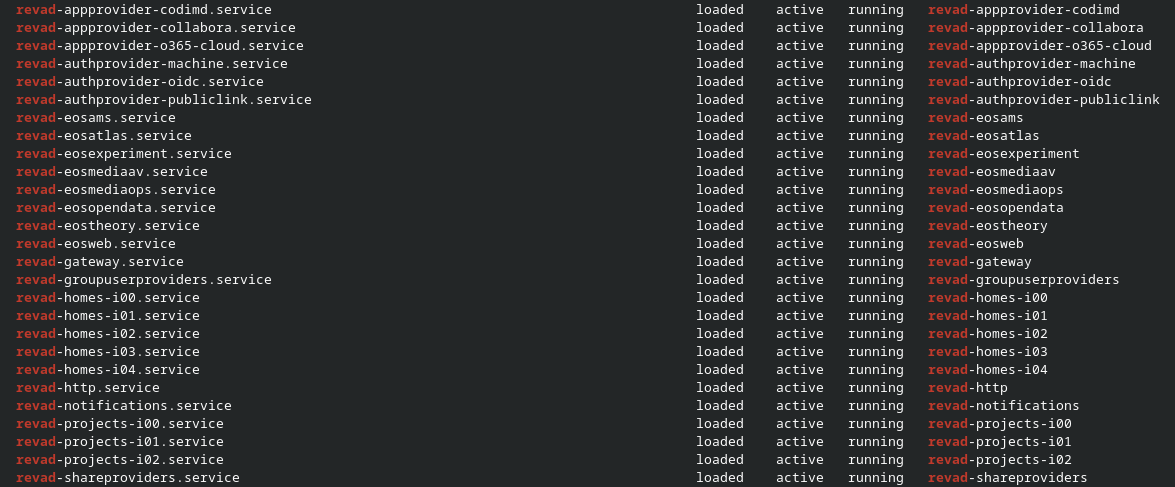
but it is perfectly possible to run everything under one daemon / process.
Systemd unit files
Our systemd unit files look like this:
[Unit]
Description=revad-<daemon>
After=network.target

[Service]
Type=simple
ExecStart=/usr/bin/revad -c /etc/revad/revad-<daemon>.toml
User=root
Group=root
LimitNOFILE=4096
StandardError=append:/var/log/revad/stderr-revad-<daemon>.log
Restart=always

[Install]
WantedBy=multi-user.target
Basic Configuration
Configuring Reva happens by creating toml files, which are usually placed under /etc/revad/<daemon>.toml
Shared config and logging
Let’s start with the easiest part: shared config. There is some config that is shared by all the different parts of the system. Shared config can be specified as follows:
[log]
output = "/var/log/revad/revad-gateway.log"
level = "debug" # Can be changed to info, warn, ...
mode = "json" # this line is optional. The default is a human-readable format

[shared]
gatewaysvc = "localhost:9142"
jwt_secret = "%__revad_jwt_secret__%"
db_engine = "mysql"
db_username = "%__db_username__%"
db_password = "%__db_password__%"
db_host = "cernbox.mysql.cern.ch"
db_port = 5504 # Note that this must be an int, not a string!
db_name = "reva"
Here,
gatewaysvcpoints to the address where the gateway runs. The default port for this is 9142, so we will keep it like this. This will be set up later.jwt_secretis the secret used for signing JWT tokens- And then there is the configuration for connecting to the database. Reva supports multiple database engines. The default is
mysql, butsqliteis also supported. In casesqliteis used, onlydb_nameneeds to be filled.
Gateway
The gateway is the central part of Reva: it’s where all requests come in. Different subsystems in Reva never talk to each other, every request gets made to the gateway. If multiple providers for a system are available (e.g. if you run multiple storage providers), the gateway is responsible for routing your request to the right one.
Instantiating the gateway happens like this:
[grpc]
address = "0.0.0.0:9142"

[grpc.services.gateway]
# Routing to providers
authregistrysvc = "localhost:9142"
storageregistrysvc = "localhost:9142"
appregistrysvc = "localhost:9142"
preferencessvc = "localhost:9142"
userprovidersvc = "localhost:9142"
groupprovidersvc = "localhost:9142"
usershareprovidersvc = "localhost:9142"
publicshareprovidersvc = "localhost:9142"
spacessvc = "localhost:9142"

# Storage
commit_share_to_storage_grant = true
home_layout = "/eos/user/{{substr 0 1 .Username}}/{{.Username}}/"
create_home_cache_ttl = 86400

# Data gateway configuration
datagateway = "https://cernbox.cern.ch/data"
transfer_shared_secret = "secret_value"
transfer_expires = 86400

# ResourceInfo cache
resource_info_cache_ttl = 60
resource_info_cache_type = "memory"

# Optional values
disable_home_creation_on_login = false # by default, a user home directory will be created on the user's first login to the system
ocm_enabled = false  # enable support for OpenCloudMesh, a federation protocol
etag_cache_ttl = 0  # TTL for etag caches.
allowed_user_agents = { "/home" = ["grpc", "desktop"] } #  contains a mapping of which user agents are allowed to make requests to storages. This can be configured per-storage.

[grpc.services.gateway.token_managers.jwt]
expires = 86400
There are quite a lot of options, so let’s dive into it. The first part has to do with the deployment model: Reva can run as multiple processes, so the gateway needs to know where all the providers are located. Since in this guide we will set up Reva in a single process, all of them will have the same address: the one of the gateway.
Now, depending on the setup you want to run, you may not need all of these providers. In fact, the only ones that you really need are:
authregistrysvc: this one will handle all the authentication methodsstorageregistrysvc: where to find storagesuserprovidersvc: provides usersgroupprovidersvc: provides groupsspacessvc: holds a database of spaces, or collaboration areas
Then there is a service for managing preferences (which allows users to save e.g. their preferred language, etc), and there are providers for user shares and public shares (with public shares being sharing via a special link).
Then we come to the second part, with options relating to storage:
commit_share_to_storage_grantdetermines if, when you share a file, whether this should also call theAddGrantoperation on the resource (which sets the ACLs on the storage). This should be set totrueusually.home_layoutdetermines the path of user’s homes. This uses Go templates. At CERN, homes look like/eos/user/m/myuser(we shard based on the first letter of the username), but for simpler setups something like/users/{{.Username}}may suffice.create_home_cache_ttldetermines how often to check if a user’s home directory should be created. This can be set to a high value, because once a user home is created this should not change anymore. Using this cache prevents stats from happening to the storage provider to determine if the home is already created.allowed_user_agents
Next up we have configuration for the data gateway. A proper explanation of the data gateway will follow; it is basically a middleman that handles uploads. Since the gateway needs to talk to it, we need to specify its endpoint here. We also need to specify a secret that is used for communication with the datagateway; you will need to put the same value in it’s configuration. Finally, transfer_expires determines how long a data transfer to the datagateway is allowed to take before it times out.
Lastly for this section, there are a number of optional options. They are annotated with their default value, these should only be needed in more complex setups.
The final part is a configuration for token managers. We only use one token type, namely jwt. It is in principle possible to add support for other tokens as well.
Auth registry
The auth registry defines how users can authenticate themselves. In this basic setup, we will only add support for bearer tokens. These are handled by an auth provider.
Reva supports a number of auth providers. In this guide, we will go over the json and oidc drivers. If you want to get started fast, the json might be easiest, while the OIDC driver is obviously recommended for production systems.
JSON
[grpc.services.authregistry]
driver = "static"

[grpc.services.authregistry.drivers.static.rules]
bearer = "localhost:9142"

[grpc.services.authprovider]
auth_manager = "json"

[grpc.services.authprovider.auth_managers.json]
users = "./users.json"
You then need to provision a JSON file like this
[
  {
    "username": "testuser",
    "id": {
      "idp": "http://localhost:20080",
      "opaque_id": "testuser",
      "type": 1
    },
    "secret": "testpass",
    "display_name": "Test User",
    "mail": "test@example.com",
    "mail_verified": true,
    "groups": ["myusers"],
    "uid_number": 1255,
    "gid_number": 123
  }
]
OIDC
If you want to provision a proper auth provider, you can use the OIDC authprovider like this:
[grpc.services.authregistry]
driver = "static"

[grpc.services.authregistry.drivers.static.rules]
bearer = "localhost:9142"

[grpc.services.authprovider]
auth_manager = "oidc"

[grpc.services.authprovider.auth_managers.oidc]
issuer = "https://auth.cern.ch/auth/realms/cern"
uid_claim = "cern_uid"
gid_claim = "cern_gid"
gatewaysvc = "localhost:9142"
Important here is to set the uid_claim and gid_claim to the correct values: Reva needs to be able to obtain the user’s uid and gid from the IdP’s response.
Storage
Reva, obviously, supports multiple storage backends. Reva has built-in support for EOS, Ceph and locally mounted filesystems. In this demo, we’ll set up the locally mounted filesystem. We plan to publish two other guides, for setting up EOS and Ceph.
The basic storage config is fairly simple: we need to set up:
- a storage registry
- a storage provider
- a spaces registry
Storage Registry
Let’s start first with the storage registry, which tracks storage providers and handles the routing to them:
[grpc.services.storageregistry]
driver = "static"

[grpc.services.storageregistry.drivers.static]
home_provider = "/home"

[grpc.services.storageregistry.drivers.static.rules]
"/localfs" = {"address" = "localhost:9142"}
There is not much to this: we map paths to storage provider addresses.
Note that we use a static storage registry here. That means that the routing rules are configured in the config itself (under grpc.services.storageregistry.drivers.static.rules). It is also possible to use a dynamic registry here. This allows you to put these routing rules in a database and update them at runtime. The config for that looks like this:
[grpc.services.storageregistry.drivers.dynamic]
# Database info also goes here, but this is set by the sharedconfig
home_path = "/home"

[grpc.services.storageregistry.drivers.dynamic.rules]
"eosproject-i00" = "localhost:9142"
"eosproject-i01" = "localhost:9142"
# Here, we do a mapping of storage mount_id's to their addresses.
# The database contains the mappings of mount paths to the mount_id's
As you can see, the dynamic driver has an extra indirection level: the config maps mount_id’s to storage provider addresses, the database maps paths to mount_ids. Database entries in the routing table look like this:
+--------------------------------------+----------------+
| path                                 | mount_id       |
+--------------------------------------+----------------+
| /eos/project/a                       | eosproject-i00 |
| /eos/project/b                       | eosproject-i01 |
+--------------------------------------+----------------+
Storage Provider
The Storage Provider, then, provides the actual storage. There is a generic part about the StorageProvider, and then the actual operations are handled by a driver. That looks like this in the config:
[grpc.services.storageprovider]
driver = "local"
mount_path = "/localfs"
mount_id = "localfs"
data_server_url = "http://localhost:38001/data"
expose_data_server = true
provides_space_type = "personal"
space_depth = 1

[grpc.services.storageprovider.drivers.local]
disable_home = false
root = "./tmp/revalocalstorage/data"
share_folder = "./tmp/revalocalstorage/shares"
In the storageprovider section, we set:
- the
driver: this will belocalfor the locally mounted file system,eosfor EOS etc - the
mount_pathis how the storage is mounted onto Reva. This will be stripped of before being sent to the driver. Some drivers, such as EOS, then have anamespace, which is tacked on before sending requests to the actual storage - the
mount_idis an ID for the mount (and is used in the routing) data_server: TODOprovides_space_typedetermines what types of spaces this provider provides. Options arepersonal(for user homes),project(for collaboration areas),explorer(for public spaces, these are visible to everyone)space_depthdetermines at what tree depth spaces start. In the CERN case, we host user homes at/eos/user/{{substr 0 1 .Username}}/{{ .Username }}, so in that casespace_depthwould be4.
Then comes the driver config:
rootpoints to where the file system is mounted on the hostshare_foldershould be some location outside of the root where shared files are kept (? TODO)- Finally, it is also possible to disable the ability to have home folders with
disable_home
Spaces Registry
Finally, the spaces registry holds a database of spaces, or collaboration areas. This information is usually stored in a database, for that you can use the following config:
[grpc.services.spacesregistry]
driver = "sql"
user_space = "/eos/user/{{substr 0 1 .Username}}/{{ .Username }}"
machine_secret = "top_secret_machine_secret"
resource_info_cache_ttl = 300
resource_info_cache_type = "memory"

[grpc.services.spacesregistry.drivers.sql]
# Note that we don't have to put any config here, because we put the database configuration in the sharedconfig.
# If you want to use another database here, you can just override that here.
The only thing that needs some explanation here is the machine_secret. This is needed for the spaces registry to query files through the gateway: the machine_secret is a secret token that it can use to become a system user, instead of passing along the current user’s auth info.
Users and Groups
The next building block we need is a userprovider and a groupprovider. The simplest way to set this up is again with a JSON driver. Then the config becomes really simple:
[grpc.services.userprovider]
driver = "json"

[grpc.services.userprovider.drivers.json]
users = "./users.json"

[grpc.services.groupprovider]
driver = "json"

[grpc.services.groupprovider.drivers.json]
groups = "./groups.json"
The users.json file is the same as the example that was given in the auth section. For groups, the file looks something like this:
[
  {
    "id": {
      "opaque_id": "myusers",
      "idp": "http://localhost:20080"
    },
    "group_name": "myusers",
    "mail": "sailing-lovers@example.org",
    "display_name": "Sailing Lovers",
    "gid_number": 123,
    "members": [
      {
        "id": {
          "idp": "http://localhost:20080",
          "opaque_id": "testuser"
        }
      }
    ]
  }
]
If you want to use a more production-ready system, you will need to integrate with your LDAP / … system. At CERN we have developed a plugin for that, this can be found here: this one queries our REST API regularly and caches the result in redis.
Sharing
If you want to allow users to:
- share resources with other users
- share resources via public links
Then you need to set up a share provider. Shares can be stored in a database, which is the easiest to set up. The set-up for this is also very easy:
[grpc.services.usershareprovider]
driver = "sql"
# Optional values:
allowed_paths_for_shares = ["^/eos/user/[a-z]/[0-9a-z\\-]+/.+", "^/eos/project/[a-z]/[0-9a-z\\-]+/.+", "^/eosdev/project/[a-z]/[0-9a-z\\-]+/.+", "^/winspaces/.+"]

[grpc.services.usershareprovider.drivers.sql]
# Database info comes from sharedconfig
# Optional values:
enable_expired_shares_cleanup = false
janitor_run_interval = 60

[grpc.services.publicshareprovider]
driver = "sql"
# Optional values:
allowed_paths_for_shares = ["^/eos/user/[a-z]/[0-9a-z\\-]+/.+", "^/eos/project/[a-z]/[0-9a-z\\-]+/.+", "^/eosdev/project/[a-z]/[0-9a-z\\-]+/.+", "^/winspaces/.+"]

[grpc.services.publicshareprovider.drivers.sql]
# Optional values:
password_hash_cost = 11 # bcrypt hash cost for passwords on public links
I have not mentioned it yet, but Reva will automatically created the right tables in the database for you. All of these values should be self-explanatory. In fact there are basically no config values that you need to set.
Testing with the CLI
Now you have a basic set up for Reva. Note that this one does not include an HTTP server yet, so for now it only supports requests over gRPC. To test our setup, we can use the reva cli. As mentioned in the introduction, reva releases contain two binaries: reva and revad. revad is the daemon: it runs the actual server. The reva binary is a CLI tool that allows you to connect over gRPC using the CS3APIs. This tool is perfect to test our setup. First, we can log in using:
reva -insecure login basic
We need -insecure since we are not using TLS for the connection. basic is the auth type: we could also log in via bearer or machine. This will then prompt for a username and password. Once signed in, a file called ~/.reva-token will be created. This file contains the token we send along with our requests; the CLI will automatically look for it.
Now you can either use the CLI directly (reva -insecure) or immediately execute a command (e.g. reva -insecure mkdir myfolder). Running help will give you a list of available commands